Team Dynamo A (Oluwadara Adedeji — UCD; Chinonso Osuji, Jidenna Okwarah, Christopher Mc Aleer — DCU) won 1st Prize at the 2025 Huawei Ireland Tech Arena for an end-to-end LLM inference system tuned on two axes at once: latency and accuracy. The schematic below is the mental model we worked from: a prompt enters, the model answers, and every design choice around it is deliberately classified under whichever axis it moves.
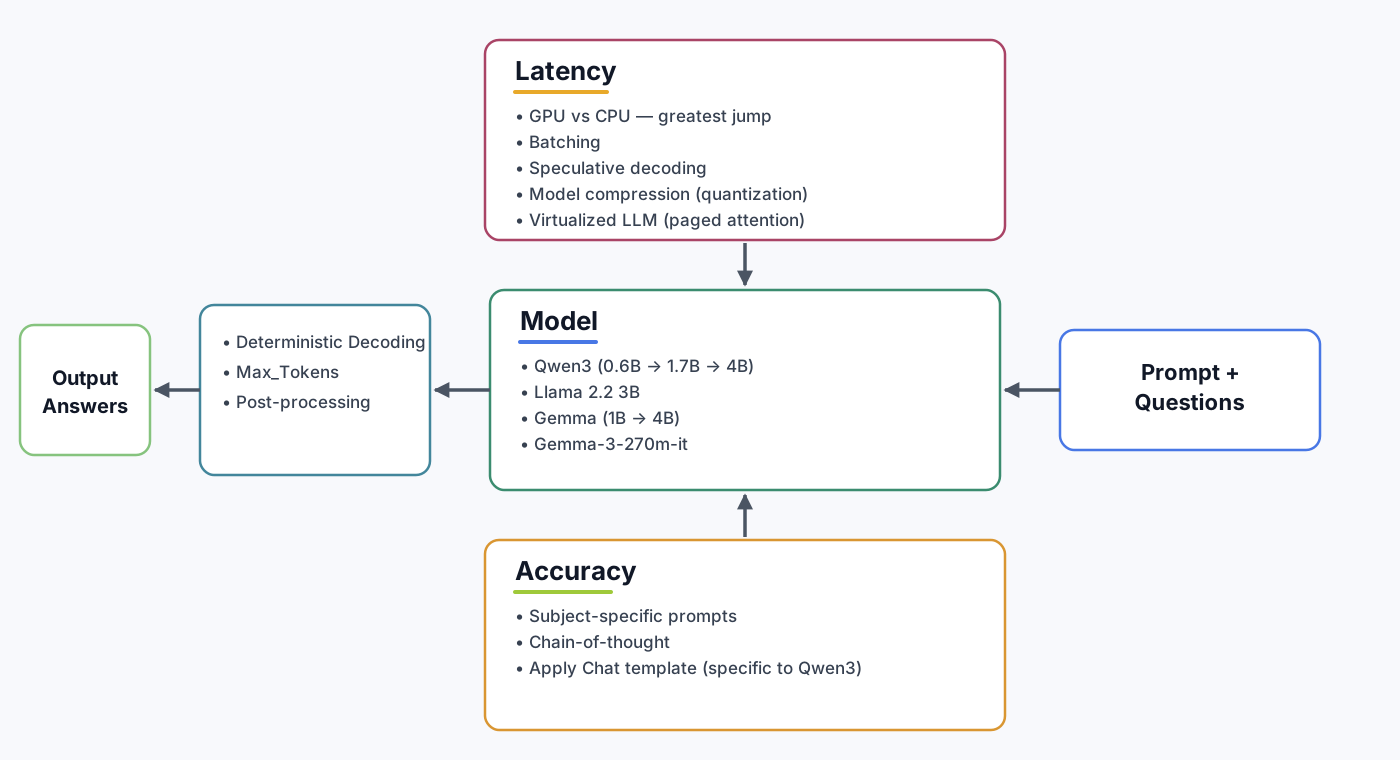
Latency levers sat around hardware and serving: GPU over CPU for the biggest jump, request batching, speculative decoding, model compression via quantization, and paged attention for a virtualized LLM runtime. Accuracy levers sat around the prompt and the decoding step: subject-specific prompts, chain-of-thought, applying the Qwen3 chat template, deterministic decoding, bounded max_tokens, and lightweight post-processing. The model slot itself was swept across Qwen3 (0.6B → 1.7B → 4B), Llama 2.2 3B, Gemma (1B → 4B), and Gemma-3-270m-it so we could pick the point on the frontier where the two axes paid off together rather than one at the other’s expense.
Press coverage: blog post.